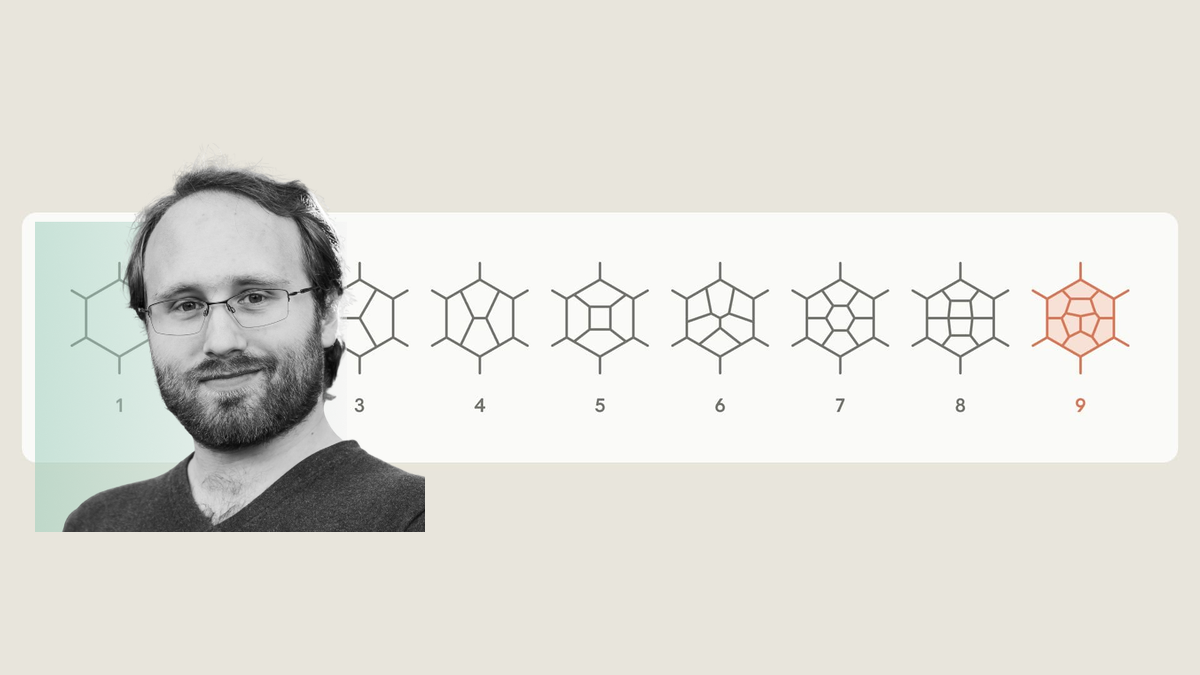


In particle physics, the term “nine rings” sounds like an abstract number, but for researchers, it represents an extremely arduous process of formula derivation and calculation. On September 25th, physicists and science authors Matt, von, and Hippel published a guest article on the Anthropic website, recounting how two physicists Anthropic managed to complete the nine-ring calculations for the six-particle amplitudes in the planar N=4 super-Yang-Mills theory with the help of Claude Science. Previous research had only progressed to eight rings, and the results for nine rings were verified by experts from other fields. The most newsworthy aspect of this story is not that a new physical law was invented out of nowhere, but rather that the researchers managed to overcome what they originally considered to be a very costly computational hurdle using existing methods.
It is necessary to first clarify the object of study. Scattering amplitudes help physicists predict the probabilities of particle interactions; the more precise the calculations, the more conducive it is to comparing theories with experiments. "Number of loops" is a marker used to approximate the complexity of calculations, and an increase in the number of loops usually leads to a sharp rise in the computational burden. However, what is being used to challenge AI this time is the N=4 super-Yang-Mills theory, which is a special theory that is easy to test, rather than a model that directly describes all particles in the real world. The results of the nine-loop calculations cannot be described as " AI discovered dark matter" or "solved a problem in the standard model." What this demonstrates is that a class of cutting-edge theoretical calculations can be advanced by new workflows.
An open challenge: How will Claude deliver the results?
Matt von Hippel Previously, a challenge was posed to AI: to push certain scattering amplitude problems to higher loop counts within the range of computationally affordable resources in academia. Liam Fitzpatrick and Siddharth Mishra from Sharma chose one of these challenges and utilized the research environment provided by Claude Science, which is centered around model configuration rules and guidelines. The guest article describes that their core task for the system was straightforward: to calculate the six-particle, nine-loop amplitudes of the super Yang-Mills theory in plane N=4, and to ensure that the system could work continuously over an extended period of time while providing regular reports. Subsequently, researchers verified the results with experts in the field. By "continuous work" here, it is not meant that no one set problems or checked answers at all; nor can it be understood that anyone could casually input a few lines of code to reliably produce a new, credible paper.
There are two approaches to this calculation. One is the existing bootstrap method within the field: first, outline the possible structure of the answer, and then gradually add theoretical constraints, known relationships, and consistency conditions to rule out those that are not feasible. The other approach utilizes indirect pathways related to form and factor. The article states that both approaches ultimately lead to the same result. Consistency across multiple paths is an important form of cross-checking, but scientific conclusions must still be solidly established through independent verification, reproducible calculations, and formal research writing. The guest author also emphasized that relevant human research teams will be responsible for publishing, interpreting, and analyzing these results; the model itself is not a substitute for the research community.
The costs also need to be considered in their entirety. The article estimates that the model invocation cost for end-users using any given computational path is about one to two thousand dollars; among these, the bootstrap path also requires approximately 96 units of CPU to run for a week, with a related computational budget of around 100 dollars. It is important not to misinterpret "one to two thousand dollars" as the total cost of the entire scientific research project, nor to overlook the fact that "96 units of CPU running for a week" cannot be completed instantaneously on a laptop. For problems that have clear objectives, can be automated, and have verifiable answers, such costs may be attractive; however, for open-ended topics that lack verification standards, this approach cannot be directly applied.
Surprisingly, there is also progress in human research. The guest author writes that not long after hearing the results of Anthropic, he learned that another group of researchers had also completed most of the work and used different forms of AI assistance. This means that it cannot be said that "humans have been at a loss for many years, and it was only Claude that found the answer for the first time." A more accurate statement would be that Claude Science demonstrated the ability to continuously code, run, correct errors, and utilize existing knowledge on a professional issue that was already close to a breakthrough. It may have shortened the distance from known methods to significant results, but it does not equate to an exclusive scientific discovery.
From "being able to answer questions" to "being able to conduct research", where exactly is the gap?
This case is interesting precisely because it lacks any mythological or exaggerated elements. The researchers began by choosing a task that had a clear definition, for which existing tools were relatively mature, and whose results could be verified by experts. The model performed exceptionally well under these conditions, indicating that one practical approach to scientific research is to be a patient computational collaborator: to understand the task, write the necessary programs, run them continuously, make adjustments when intermediate results are incorrect, and then provide experts with clear enough materials to review. The value here lies not only in the final formula but also in the reduction of the time humans spend on tedious calculations and engineering details.
However, from theoretical models to practical experimental predictions, there are still several hurdles that cannot be bypassed. Real-world problems may not have such a clean mathematical structure, data can contain measurement errors, and new results may lack independent means of verification. Even if two sets of algorithms yield the same answer, it is necessary to determine whether they are based on the same erroneous assumptions. Researchers also need to clarify which decisions are made by humans, which steps are automated by systems, and what the computational power and software versions are, in order for other teams to be able to replicate the experiments. Without this information, impressive demonstrations are unlikely to be transformed into accumulable scientific knowledge.
The guest author did not claim to have obtained an answer regarding “general artificial intelligence” as a result of this. What he saw was a previously underestimated opportunity: some tasks that were considered to require beyond ordinary computing resources might actually just need better software engineering and more sustainable automation. For the AI industry, this is a conclusion that deserves serious consideration more than the statement “models surpass physicists.” Nine Rings Computing demonstrates that when the boundaries of problems, verification paths, and research responsibilities are clear, models can advance scientific research; however, whether they can replicate this performance on more irregular and experimentally closer physical problems will require the next batch of public and verifiable cases.