



Ant Birdling opens-source Ling-3.1-flash AI models, supporting up to 1M contexts
The Block
51m ago
Ai Focus
Ant Bird announced yesterday the open-sourcing of the Ling-3.1-flash model, which has a total of about 560B parameters, with each Token activation costing approximately 25B, and supports up to 1M contexts. The article also introduces its public evaluation performance, local deployment quantization solutions, long-context parallel inference solutions, as well as the limited-time discount prices for OpenRouter and Ling Studio.
Helpful
No.Help

Ant Birdling announced yesterday the open-sourcing of the Ling-3.1-flash model. The total parameters of Ling-3.1-flash are approximately 560B, with each Token activation costing about 25B, and it supports up to 1M contexts.
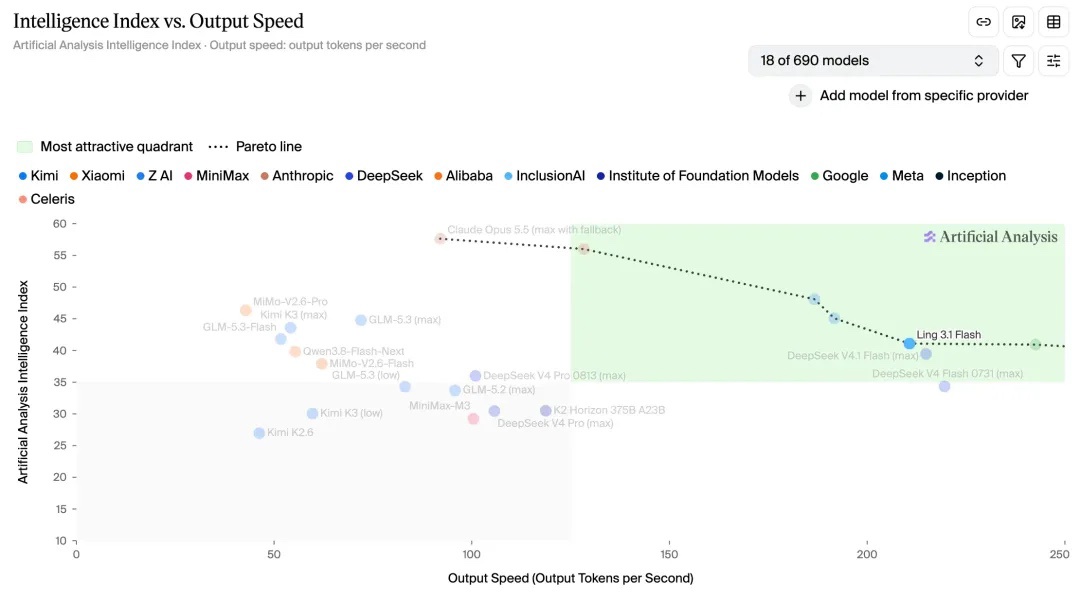
In the public evaluation of Artificial Analysis, the intelligence index of Ling-3.1-flash is 41, with an output speed of approximately 210 Token per second.
For local deployment, the team adopted MXFP4 quantization for routed and experts, and maintained block-FP8. The weight occupancy was reduced from approximately 534GB to 292GB. In the corresponding Hopper GPU test configuration, the service deployment was reduced from 8 cards to 4 cards, allowing teams with server-level GPU to run models with fewer cards; however, actual requirements may still vary depending on context, concurrency, and service configuration.

For processing long documents, the team provides a parallel reasoning solution for long contexts ( PCP / DCP ); the tool calls have also enhanced support for JSON Schema, facilitating integration with existing business interfaces.

Enterprise knowledge Q&A and office assistants often need to read longer materials first, but users still hope to see responses as quickly as possible. The team has reduced inference overhead through operator fusion and DSpark speculative decoding: in a simulated production request with an average input of about 25.47K Token, an average output of about 224 Token, and a cache hit rate of 76%, the average first Token time under an 8-core Hopper configuration was 604 milliseconds, and the average interval between consecutive outputs Token was 3.28 milliseconds. This provides a test reference for interactive responses after long material inputs.

For business systems that provide continuous services, it is also necessary to evaluate within a fixed GPU budget how many requests a single instance can handle. In a throughput test with an average input of about 8.5K Token and an average output of about 800 Token using 4 cards Hopper, the model achieved approximately 1.36 QPS. At the same time, it met the test constraints of an initial Token time of less than 3 seconds and an interval between consecutive outputs of less than 70 milliseconds Token. This provides a reference for capacity planning for self-deployed systems.

In terms of online experience, Ling-3.1-flash currently offers a limited-time 25% discount. The price after the discount is as follows:

  • OpenRouter (denominated in US dollars): Input 0.075 USD; Output 0.225 USD; Cache read 0.015 USD.
  • Ling Studio (denominated in RMB): Input 0.5 yuan; Output 1.5 yuan; Cache read 0.1 yuan.

IT Home with Open Source Links:

  • Hugging Face : https :// huggingface.co / inclusionAI / Ling-3.1-flash
  • ModelScope : https :// modelscope.cn / models / inclusionAI / Ling-3.1-flash

Related Reading: "Ant Birdling Releases Ling-3.1-flash Model: Approximately 560B Total Parameters, 25B Activation Parameters"

Tip
$0
Like
0
Save
0
Views 15
WalletJYS reminds readers to view blockchain rationally, stay aware of risks, and beware of virtual token issuance and speculation. All content on this site represents market information or related viewpoints only and does not constitute any form of investment advice. If you find sensitive content, please click“Report”,and we will handle it promptly。
Submit
Comment 0
Hot
Latest
No comments yet. Be the first!
Related
Bitcoin, BNB, HYPE, and ADA Price Analysis: Can Buyers Regain Control?
Bitcoin tests support around $80,000, BNB hovers above $700, HYPE holds the key support around $77, while ADA slides towards the 100-day moving average. The article analyzes the recent trends of four crypto assets, their moving average positions, and possible support and resistance zones.
U.Today
·2026-10-16 08:16:35
12
OpenAI may struggle to meet advertising revenue targets and is aggressively recruiting talents from Google and Meta
OpenAI has intensively launched advertising products, lowered pricing, and undertaken large-scale recruitment in recent months, driving a rapid increase in the number of advertising clients. By the end of August, the annual advertising revenue reached $1 billion. However, reports citing informed sources and research institutions suggest that the company's goal of achieving $2.4 billion in advertising revenue by 2026, which was set earlier this year with investors, is likely to be difficult to achieve.
The Block
·2026-10-16 07:56:18
19
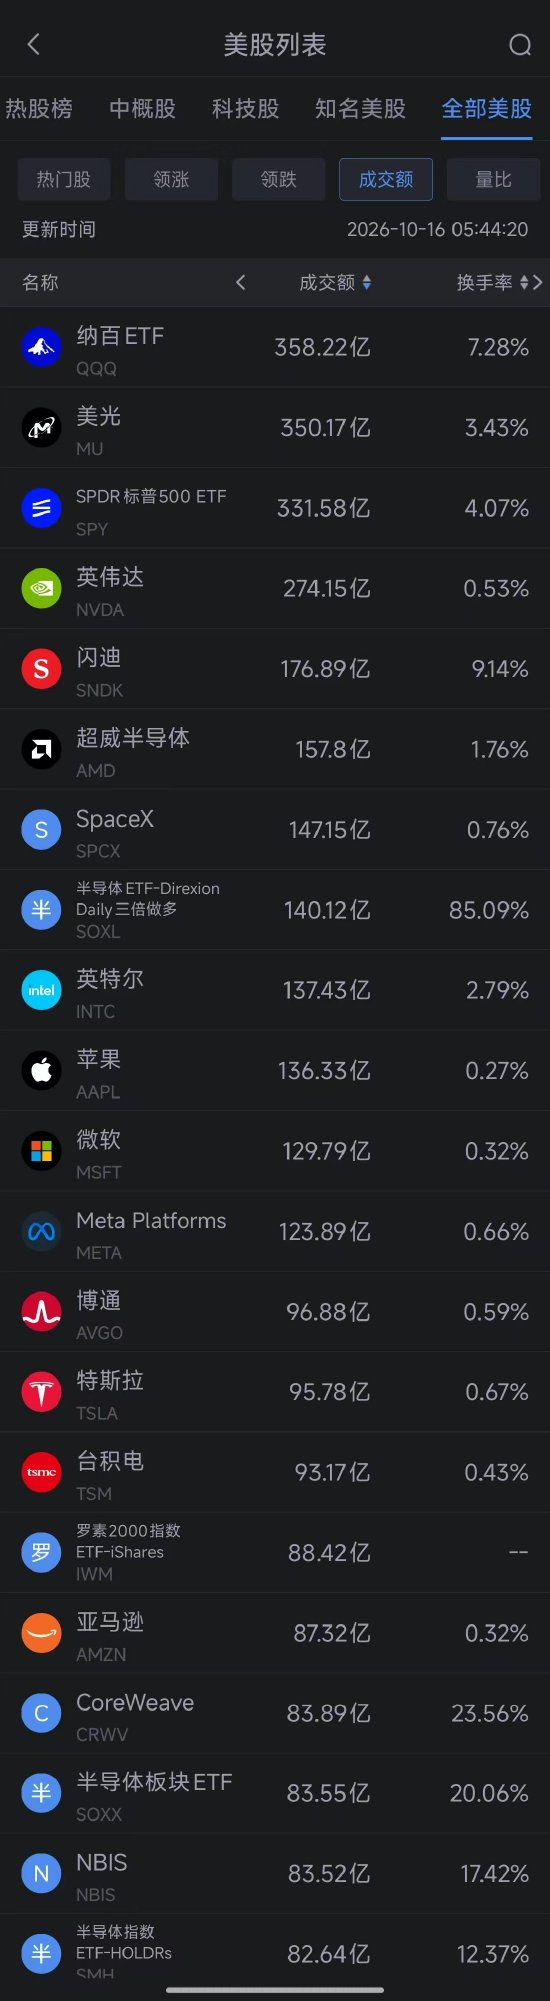
Top 20 US stock traders on October 16: CoreWeave rose 5.94% Jensen Huang says there's no need for NVIDIA to cover its losses
Among the top 20 largest U.S. stock trades, NVIDIA fell 1.84% with trading volume of $27.415 billion; Micron Technology rose 1.87% with trading volume of $35.017 billion; CoreWeave rose 5.94% with trading volume of $8.389 billion. Jensen Huang stated that CoreWeave's financial strength is increasing, and there is no need for NVIDIA to provide support for them.
The Block
·2026-10-16 07:46:40
18
The Dow Jones rose by over 550 points, medical and consumer stocks strengthened, chip stocks continued to decline, Chinese concept stocks generally rose, and U.S. oil prices increased by more than 3%
U.S. stock market indexes closed higher on Thursday, with the Dow Jones Industrial Average rising more than 1%. In September, the PPI in the U.S. exceeded expectations, but U.S. Treasury yields fell, and funds shifted to the healthcare and consumer sectors, while chip stocks continued to face pressure. The NASDAQ Golden Dragon China Index rose 1.96%, WTI crude oil rose more than 3%, and gold and silver rebounded.
The Block
·2026-10-16 07:46:37
16
Microsoft AI claims that a person using one-quarter of their computing power defeated OpenAI
Microsoft CEO Mustafa Suleiman stated that the company's internal model is superior to a similar product from OpenAI, and only a quarter of the computing power used by that product was required for training. On that day, Microsoft also announced MAI-Base-2 and claimed that it outperforms some OpenAI and DeepSeek models in private tests as well.
Businessinsider
·2026-10-16 07:46:36
18
View More