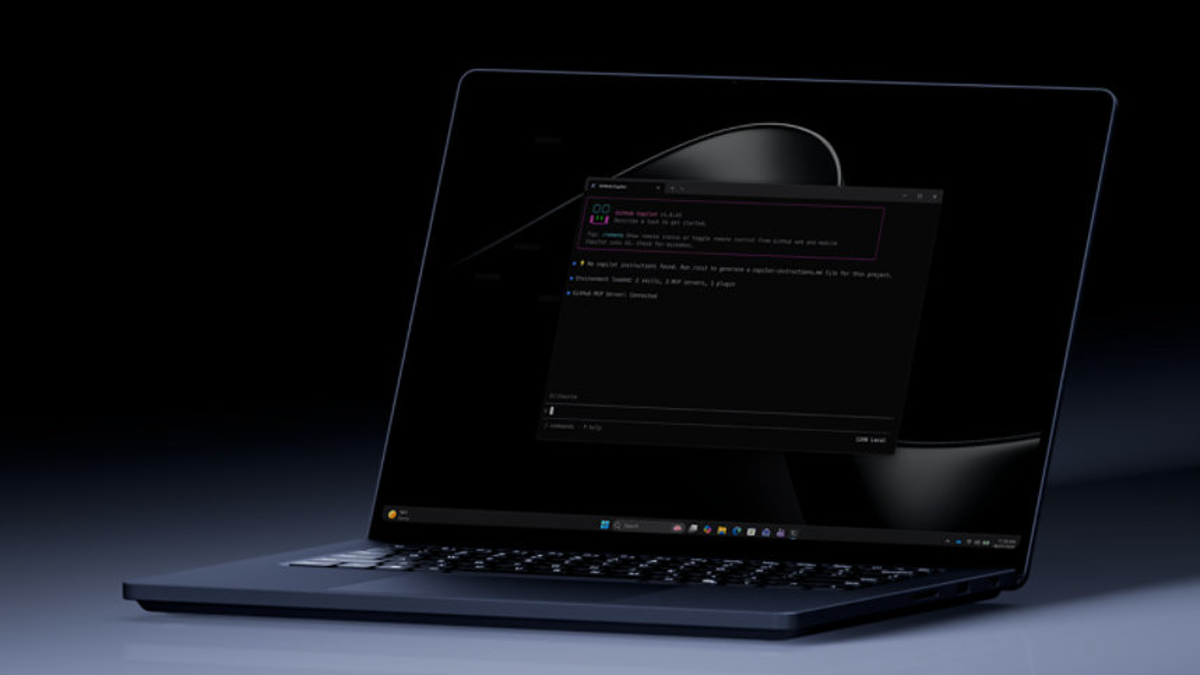











The Microsoft Store lists the release dates for Surface Laptop Ultra, for, and Business as October 16th. The most prominent features of this new product are its NVIDIA RTX Spark chip, up to 128GB of unified memory, and the hardware capacity to run larger models locally on the device. Microsoft claims that the specified configuration can provide approximately one trillion AI calculations per second, supporting models with up to 120 billion parameters; however, these are product capability descriptions under specific conditions. It does not mean that all enterprise applications will be able to achieve the same speed in offline mode, nor does it imply that purchasing a computer alone will complete an enterprise-level AI transformation.
This matter is worth paying attention to, not because the notebook now has an additional AI chip, but because the boundaries of local inference are shifting. In the past, when companies chose large models, they would typically consider factors such as cloud call prices, network latency, and whether data could be transferred out of the cloud. Now, hardware manufacturers are attempting to bring part of the inference process, prototype development, and multimodal processing back to employees' desktops. For teams that need to frequently work with internal documents, code libraries, or design materials, this represents a new deployment option. However, how much cost can actually be saved and whether it can replace existing cloud services still needs to be tested based on actual workloads.
Back to the real workflow from the parameter upper limit
The models listed on the Microsoft official website use RTX Spark N1X, which integrates CPU, RTX GPU, and NPU; up to 128GB of unified memory can be shared by different processing units. The significance of unified memory is not just an increase in the numerical value, but rather that model weights and runtime data can have more available space within a single device. Previously, many local applications were limited by the amount of video memory, and even if developers had sufficient computing resources, they had to quantify models, split tasks, or resort to the cloud. The larger shared memory has improved this constraint, but the extent of improvement still depends on model accuracy, context length, concurrent tasks, and the software stack.
The "up to 120 billion parameters" mentioned on the product page should be understood as the boundary of the model scale that the device can handle, rather than a performance guarantee. The same model may have significantly different throughput and wait times when used for short-answer questions, long-document retrieval, image understanding, and continuous tool calls. When making purchases, enterprises should not only ask whether the model can be loaded but also consider factors such as the initial response time, output per second, temperature and power consumption during continuous tasks, and whether the user experience will still be maintained when employees use it simultaneously in video conferences, browsers, and local development environments. Microsoft also includes information about heat dissipation capabilities and battery life on their pages, indicating that these aspects under continuous load are not negligible details.
This device is available for purchase starting from $2,749.99 and is clearly a high-end product designed for professional and enterprise scenarios. When evaluating the return on investment, one cannot simply compare the unit price of a single cloud API call with the price of a computer. Hardware comes with costs associated with depreciation, maintenance, device management, and security updates; whereas the cloud offers advantages such as flexible scaling, centralized management, and usage-based billing. Local solutions may be more cost-effective for tasks that are high-frequency, predictable, and sensitive to data residency, but the cloud is still more suitable for large-scale parallel reasoning that occurs suddenly and for scenarios that require the latest cutting-edge models. In the end, most enterprises may end up adopting a hybrid architecture, rather than choosing one over the other exclusively.
Security discussions also need to be anchored in specific boundaries. Local processing can reduce the number of times certain raw materials leave the terminal, but it does not automatically solve issues such as terminal loss, malware, model output leakage, or misuse of permissions. If an employee hands over sensitive files to a local model, the company still needs to determine how to store file indices, whether to retain chat history, which systems plugins can access, and how to clear data after the device is discarded. Moving the point of inference from the cloud to the desktop only changes the distribution of risks; it does not eliminate them.
Who will truly benefit first after this sale begins?
Software development and internal knowledge processing may be the most feasible directions for conducting initial experiments. Developers can run code assistance, log analysis, or small-scale proxy processes locally to reduce waiting times for transmitting large amounts of data. Legal, design, and research teams may also keep more sensitive materials on managed devices, first using local models for classification, summarization, and retrieval, before sending the parts that require more advanced reasoning to a controlled cloud environment. The key phrase here is “conduct initial experiments”: product pages showcase the potential of hardware but do not provide unified evidence of effectiveness across various industries, models, and software versions.
The procurement department should also distinguish between device availability and enterprise manageability. Just being able to run models on machines is the first step; the IT team also needs to unify model versions, patches, and licenses to ensure that the same prompts produce traceable results on different employees' devices. If a model caches a large amount of enterprise data locally, the processes for revoking permissions and replacing devices can even be more complicated than using cloud-based tools alone. A good demonstration video cannot replace an inter-departmental operations manual.
For the AI ecosystem, a more valuable development is the expansion of computing power supply from "centralized deployment in data centers" to "shared responsibility by clouds and endpoints." NVIDIA and Microsoft have combined chips, memory, cooling systems, and Windows devices to encourage model developers to optimize their models for local environments; model manufacturers, in turn, are motivated to provide more flexible quantization, routing, and privacy settings. If the supporting software does not keep up, even the most impressive hardware specifications may end up being used only as demonstration tools for a few technical teams, rather than as everyday production tools.
Therefore, the most pragmatic way to evaluate Surface Laptop Ultra is to compare three sets of tasks under the same conditions: one set involves local retrieval of real corporate documents, another requires internet connectivity and external tools for a longer process, and the third set deals with high concurrency or challenges posed by large models. By recording completion rates, latency, power consumption, manual review times, and total cost of ownership, we can then decide which aspects should remain on the device. The launch on October 16th provided a concrete product for such testing, but whether local AI can become a standard feature for enterprises still depends on these measurable work indicators, rather than the peak figures shown on promotional pages.
Source: Microsoft Official Product Page https :// www.microsoft.com / en-us /d/ surface-laptop-ultra-for-business /8wg5vqp0x4d1.