Google announced yesterday the launch of Gemini Decisions API Rapid Multimodal Decision-making, which is driven by a new Gemini Decision 1 model. This API can perform up to 1,000 true/false judgments, option selections, and standard evaluations on text, images, videos, and PDF content in a single rapid processing session.
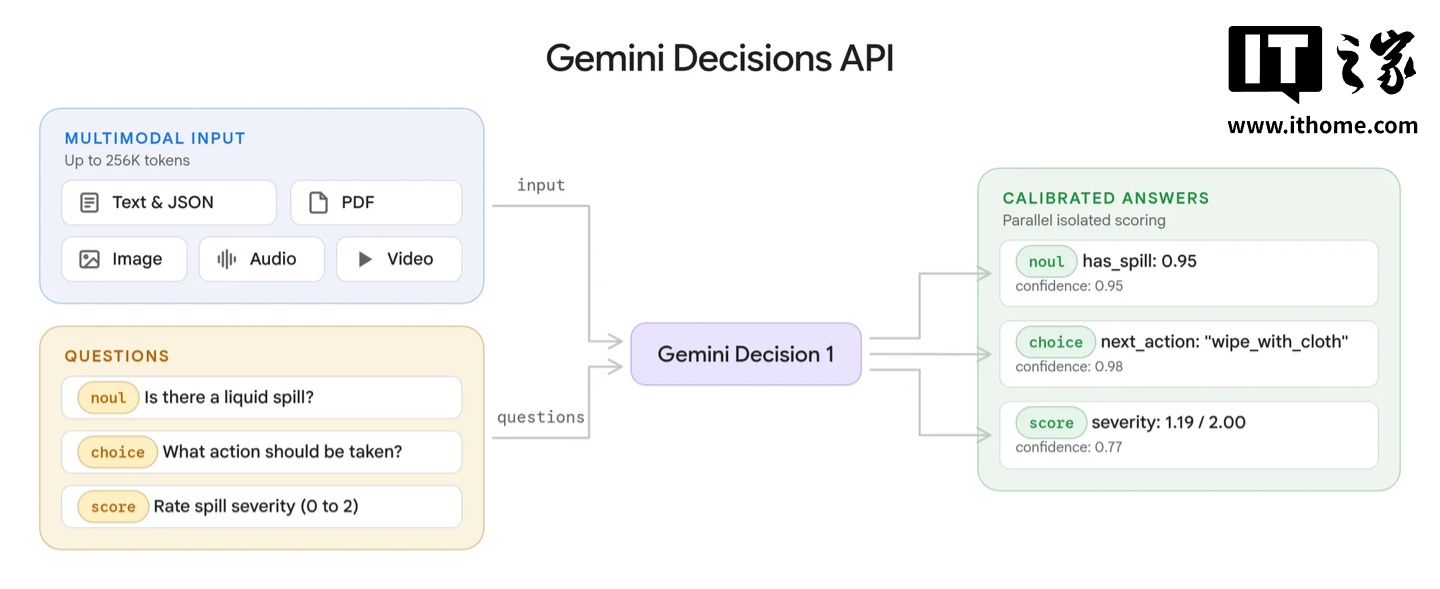
According to the introduction, Gemini Decisions API is specifically designed for decision-making tasks such as tool selection, strategy checking, model routing, and context quality assessment. Developers can input multimodal content that includes text, images, audio, video, and PDF, with a maximum support of 256K Tokens. They can also pose up to 1000 independent questions regarding this content.
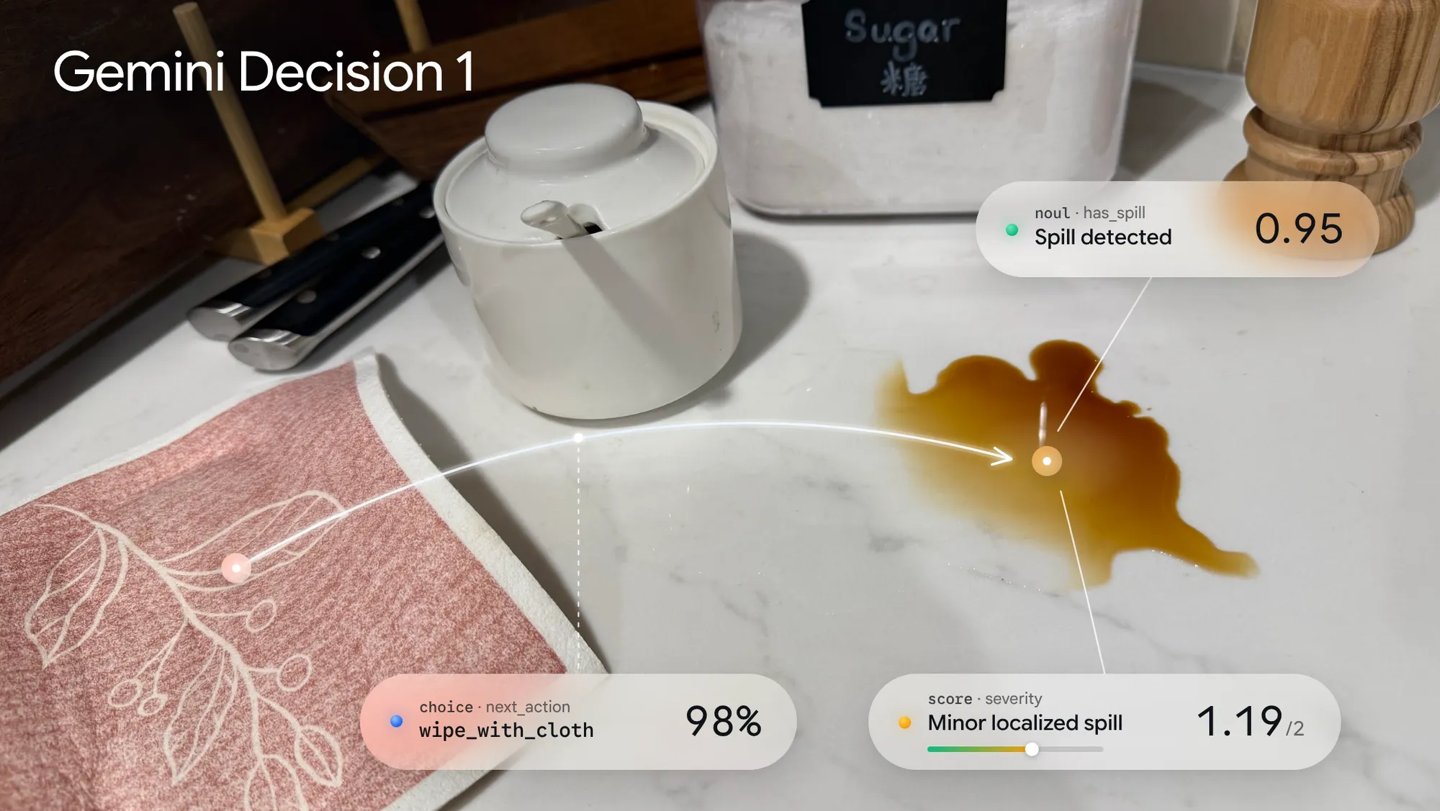
At the same time, Gemini Decision 1 will score the candidate options through a single forward calculation and return a probability and confidence score. The delay for the entire processing is between 150 and 250 milliseconds. The input fee is 0.10 US dollars per 1 million Tokens, and there is no charge for the output Tokens.
In addition, this API is built upon the native multi-modal architecture of Gemini. Developers can combine content from different modalities within the same input, such as combining call recordings with account metadata, or putting scanned PDF claim files alongside damaged photos. Furthermore, it is possible to adjust the resolution of image and video inputs to control visual details and Token costs.
Currently, this API is available at Google AI Studio. Developers can obtain a free quota for prototype development.