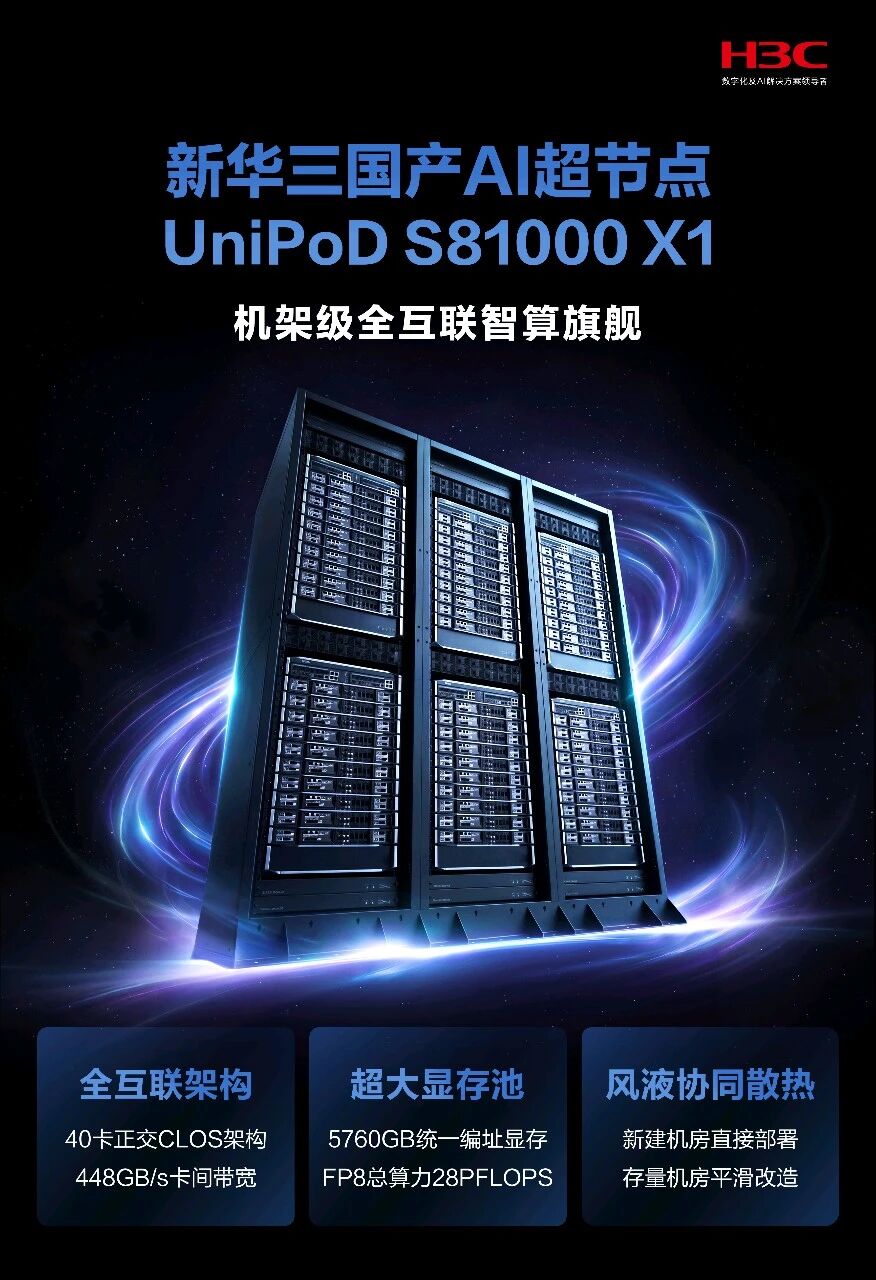
New Unigroup's subsidiary, H3C, released a rack-level fully interconnected intelligent computing product yesterday: UniPoD S81000 X1 Super Node. This product supports up to 40 domestically produced acceleration cards per Scale-Up domain, and achieves a first-level CLOS fully interconnected topology through 4 dedicated Scale-Up switches Tray. The bandwidth between any two cards can reach 448GB/s.
S81000 adopts an orthogonal connection design, where computing nodes are directly connected to switching nodes via high-speed connectors, eliminating the need for cables and backplanes. The product uses pure electrical interconnection without optical modules, and manufacturers claim that this has increased physical reliability by 10 times.
In terms of video memory and computing power, 40 cards are aggregated to form a 5760GB video memory pool with unified addressing, supporting FP8 precision (Note from IT: FP8 is an 8-bit floating-point format, commonly used in AI training and inference acceleration), with a total computing power of up to 28P FLOPS.
The product is compatible with 19-inch standard cabinets and supports decoupled delivery of cabinets. A single cabinet can deploy up to 2 sets of 40-card super nodes. The cooling system adopts a collaborative architecture that primarily uses liquid cooling, with compatibility for both liquid and air cooling methods.
Traditional 8-card servers rely on Ethernet stacking for networking, with inter-card communication having latency in the microsecond range and bandwidth of hundreds of Gb /s. Under the communication requirements of trillion-parameter MoE large models, a significant amount of GPU time is spent waiting for data. In addition, agents operate 24/7, and the failure rate of multiple Agent serial connections is notably high. Traditional cluster components are complex, fault localization is slow, and operational and maintenance costs increase linearly with scale.
H3C stated that as AI agents accelerate their penetration into enterprise workflows, these agents place triple pressure on underlying computing resources. A single task Token consumes tens of thousands to millions of resources, which is dozens of times higher than in traditional dialogue scenarios.